I’m looking at adding a GPU to my XCP-NG machine and wanted some feedback on recommendations.
I am going to be using a Dell R630 for XCP-NG and currently have a Tesla P4 GPU, but want something slightly larger since I’ll want to host a local LLM, do video transcoding and other smaller GPU based tasks within the different services I plan to self-host.
My idea was to purchase a Tesla T4 since it’s 2x the GPU capacity, but I recently found that there is an Nvidia A2 for a slightly better price, same 16GB GPU RAM though.
I’m definitely open to hearing y’alls opinion regarding this, and if there are any other recommendations I’m open to hearing them!
I was actually considering that option too, so the AI stuff lives on a single GPU and the rest of the work goes on the other GPU, or just have the GPU passthrough on xcp-ng for all of my VMs so they can share both GPUs.
It does look like I can use Riser 2 and Riser 3 in my R630 for this too. It’ll negotiate down from the A2’s Gen 4 to the R630 Gen 3 PCIe speeds, but that’ll be sufficient for the stuff I intend on doing.
Hi @angel - be aware that you can only pass a PCIe device (your GPU) through to a single VM. Once that VM ‘owns’ the PCIe device, no other VMs can use that same PCIe device.
You mentioned LLM, transcoding, and other smaller GPU tasks. I’ve done something similar, where I bought a RTX 2000 Ada, passed that through to a Linux VM, and installed all my services on that one VM (Ollama, OpenwebUI, Jellyfin). I kept the VM’s virtual disk to just a 20GB OS, and stored all the models, apps and media elsewhere, to keep it light and easy to backup/recover.
If you can get multiple GPUs, great - pass them through to different VMs and split the workloads. Pricing is insane so you’re right to focus on VRAM, even on older cards. Favour the GPU memory over the GPU performance - but all within balance and all depending on what you’re expecting.
So I’m just about wrapped up migrating my docker server (ubuntu bare metal with docker running a few containers) over to xcp-ng.
I ended up keeping my Tesla P4 and put it in my “arr” container, and threw immich on there as a dedicated GPU.
After going back and forth a bit between the Tesla T4 and Nvidia A2 I decided with the T4 since the overall bandwidth proves to be better for local LLM use.
I may consider a third GPU in the future (for better plex streams) if the tdarr conversions do not go as planned, but that’ll take about a month to transcode my library.
Since I’ve been leaning into frontier models a bit for my day-to-day work I also made it a point to have AI assist in the transition and was able to get it done smoothly which was awesome so I ended up doing something similar to Tom here Self-Hosted SSL Simplified: Nginx Proxy Manager [YouTube Release]
but I used caddy and have a build step for it that any changes get pushed to my Gitea server then deployed within the workflow automation.
With all that being said, I may end up moving everything from the R630 server to a R730XD LFF I have (once I move the TrueNAS hardware to the 740XD I have ready to go).
I went with an Intel Arc Pro B50 due to it’s excellent SR-IOV driver support. I’m using Proxmox and so I was able to install the required drivers on the host but I don’t know if XCP-ng has drivers with that support yet. I would imagine it does.
What is your primary use-case for it too if you don’t mind me asking. I briefly looked into the Arc series and was unable to find any real information regarding its use for LLMs and speed performances, although it seemed like a fairly good upgrade to the P4 I currently have for my arr stack.
Do you mind installing bonsai (PrismML — Announcing Bonsai 27B: The First 27B-Class Model to Run on a Phone) on your llama cpp and running a general prompt to see the rough t/s there? That’s the one I’ve been testing between my laptop and this ai vm, where the VM (using the T4) is getting around 7-9 t/s for that specific model. It’s great for coding, but pretty slow to execute… ComfyUI generation seems pretty decent.
If you don’t mind, did you pay MSRP for it or closer to the current MicroCenter pricing? Basically seems like great GPU after reading your post and I may need to check out if I can return my T4 hah.
That’s 6x faster than my little device. I’m using an HP T740 with Vulkan drivers and running LocalAI in the Vulkan docker image. I may look around for a low profile graphics card that’s decent and see what it might do. The 30 t/s would be nice for what I’m doing.
I tried both Ternary-Bonsai-27B-Q2_0.gguf and Ternary-Bonsai-27B-PQ2_0.gguf but get errors like “gguf_init_from_reader: tensor ‘output.weight’ has invalid ggml type 142. should be in [0, 43)”
According to the WWW: This error indicates that the stockllama.cpp engine does not recognize the specific ternary quantization format used in the model file. The GGUF file contains a tensor with ggml type 142 (which corresponds to PQ2_0 ternary quantization), but the standard llama.cpp build only supports types in the range [0, 43).
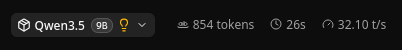
I pointed Grok/Claude to install the llama.cpp on the VM and got them running that way. Not sure if I’d recommend you doing the same since you have your stack already built and working, but I’ll try that qwen 9b model and report back the speed for a general prompt too.
Thermal Throttle was happening but here was the prompt:
You are a senior Python engineer. Write a concise, production-ready function to solve the problem below.
Constraints:
- Include explicit type hints.
- Include a docstring with a brief description and edge cases.
- Use built-in modules or common libraries only.
- Output ONLY valid executable Python code wrapped in ```python and ``` blocks. No explanations.
Problem:
Write a function `top_frequent_words(text: str, n: int) -> list[str]` that returns the top `n` most frequent words in a string, ordered by frequency high to low. If frequencies are tied, order them alphabetically. Case-insensitive. Exclude punctuation.