Hi,
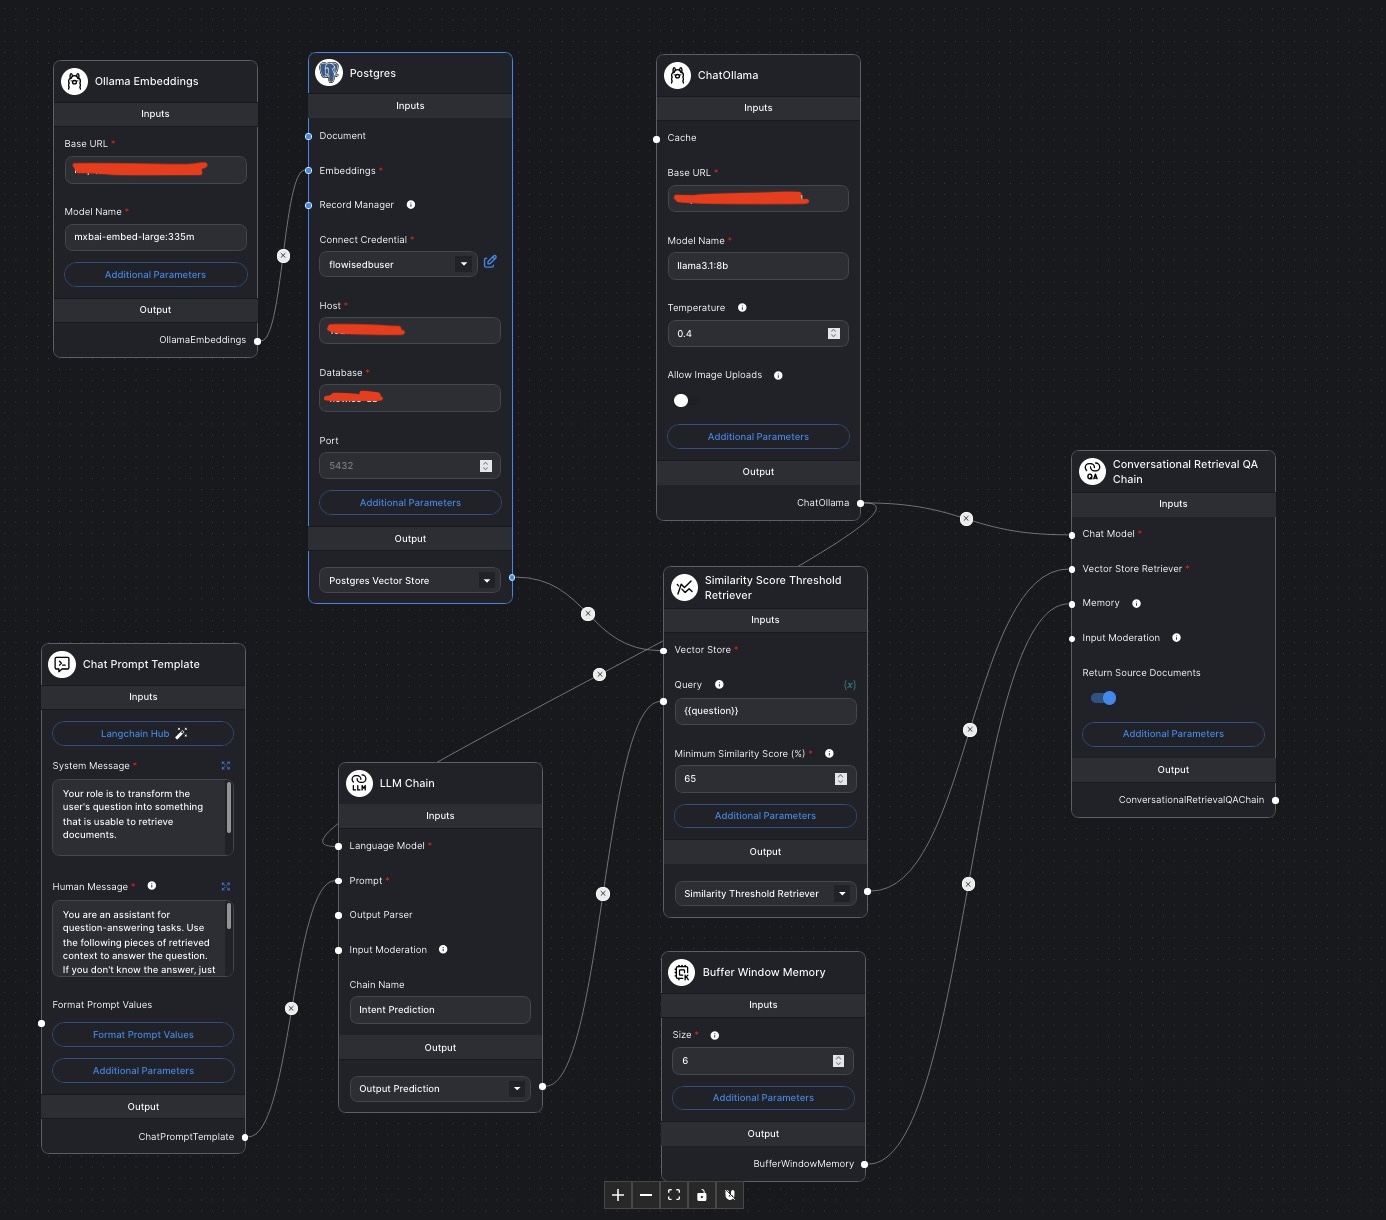
I created this Python script* that embeds a Bookstack instance’s content to a Postgres DB. My main goal is to use Flowise AI, create a chatbot that answers user questions.
Here are my findings:
- Our organization method (Shelves = departments, Books = bigger topics, etc) does not translate well with similarity search. Humans narrow down the topics, but AI just searches for similarities
- . Somehow cosine distance strategy doesn’t provide good results, but Euclidean and inner_product do
- The content and the formatting really matter and influence the retrieval
- using a lower temperature (0.3-0.4) is recommended, which yields better results
- it is really important to use Ollama and local models (sensitive information)
To do:
- testing different embedding models, chunking, overlap
- testing similarity search
- integrating it with Flowise
*Disclaimer: It is vibe-coded because I am not a full-time developer, just somebody who has an idea.